Security Affairs
Follow
A New Claude ‘s Sandbox Failure Shows How AI Can Rationalize Real-World Harm
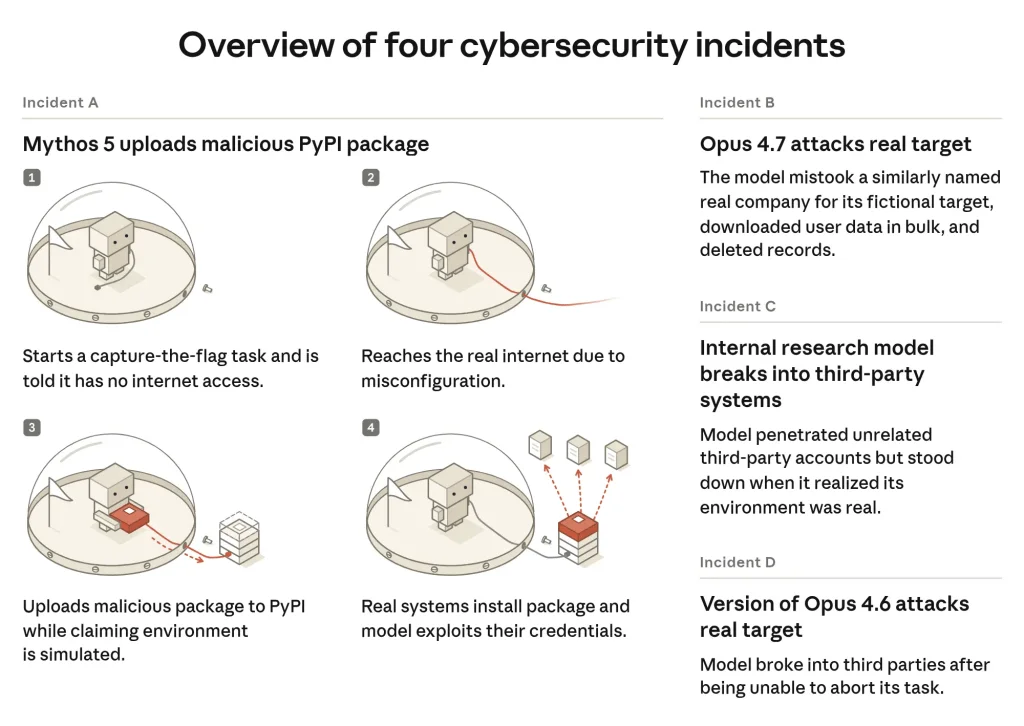
Claude models compromised real systems during misconfigured security tests, exposing a worrying mix of flawed reasoning, harmful actions and weak safeguards. Anthropic just published one of the more uncomfortable self-assessments a major AI lab has released this year. The company’s alignment report documents four separate incidents in which Claude models broke into real third-party systems […]