Google Cloud Blog
Follow
Announcing llm-d 1.0: Open distributed inference for agents on Google Cloud TPUs and GPUs
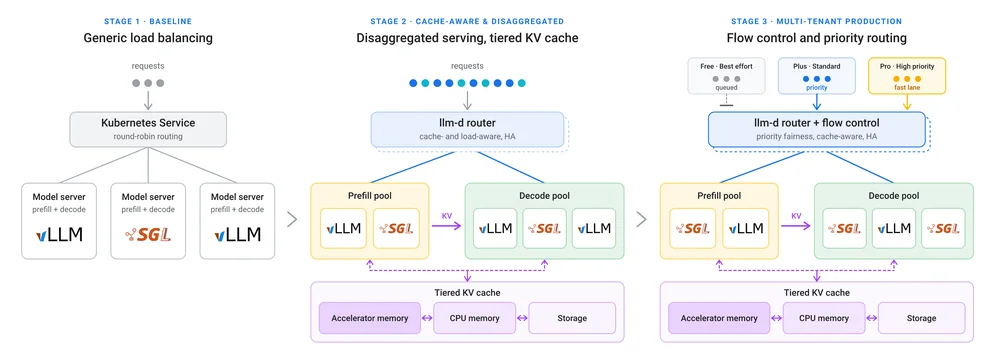
Today marks the release of llm-d 1.0, an open-source, Kubernetes-native stack for distributed LLM inference, developed by a community including Google, Red Hat, and IBM. This project integrates the PyTorch and Kubernetes communities to address evolving inference needs. Modern agent-based workloads, unlike simpler chat interactions, involve multi-step processes, tool usage, and bursty traffic patterns. Serving these on single machines or with basic load balancers proves inefficient, leading to duplicated computations and stalled interactive users. llm-d transforms clusters into coordinated serving pools, demonstrated with 1,000 agents on a single endpoint. Key features include cache-aware routing and tiered KV cache to maintain agent context and flow control to prioritize interactive requests during traffic bursts. Version 1.0 offers multi-tenant quality of service through priority-aware flow control and a stable foundation with hardened APIs. It also enables safer upgrades with high availability and zero-downtime updates, alongside agent-aware serving capabilities for context reuse. Expanded TPU integration provides native PyTorch model serving with TorchTPU time-slicing for improved throughput and utilization. llm-d components are composable, allowing users to adopt only necessary serving elements. This stack connects Kubernetes primitives, PyTorch serving engines, and accelerator-aware scheduling for a flexible production environment.