Google Cloud Blog
Follow
Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo
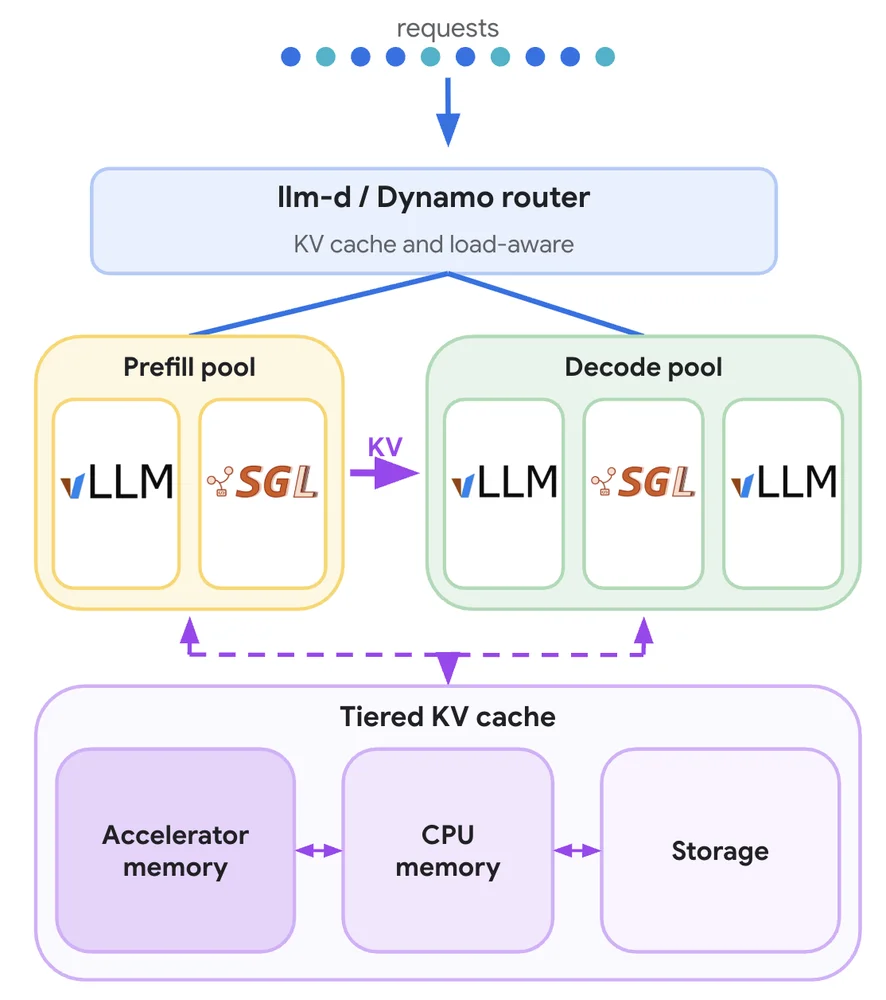
Reflection has launched Beam, an open-weight model designed for advanced software engineering and long-horizon agentic tasks. Beam operates under an Apache 2.0 license and offers impressive inference efficiency for models in its parameter class. Google Cloud announced immediate support for Beam, providing deployment recipes on their AI Hypercomputer and NVIDIA AI Infrastructure. Together with Reflection, Google Cloud optimized Beam's performance using llm-d and NVIDIA Dynamo for enhanced serving. Deploying Beam on Google Cloud resulted in significantly higher performance and lower latency for agentic workloads. The release emphasizes compounding model and system efficiency, leading to greater throughput and reduced latency for agents. High-efficiency multi-turn serving is achieved through advanced techniques like KV-cache-aware routing and speculative decoding. Developers can now benefit from turnkey optimized deployments for agentic workloads with ease. Scaling inference for agentic tasks requires optimizations at both the model and serving system layers. Beam's unique architecture, activating only a fraction of its parameters per token, drastically reduces compute requirements. The serving stack addresses bottlenecks like prefill compute and KV cache capacity in long-context scenarios. This jointly developed solution aims to empower developers with powerful and efficient AI tools.