Google Cloud Blog
Follow
How Visko streams real-time world models on Google Cloud TPUs
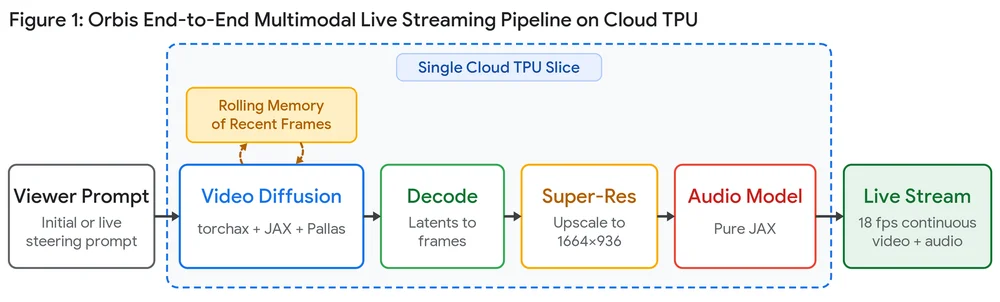
Generative AI startups are now developing interactive, real-time worlds instead of just static clips. Visko collaborated with Google Cloud TPU engineers to deploy its live world model, Orbis, on Cloud TPUs in just 30 days. Serving a live world model presents a unique challenge of beating a strict real-time clock, unlike offline video generation. Every video and audio chunk must render before the previous one finishes to avoid freezing the world. Visko's Orbis streams live video from a single prompt and allows viewers to dynamically steer the scene in real time. The teams successfully deployed Visko's end-to-end inference pipeline, including video generation, upscaling, and audio, onto a single Cloud TPU slice. They achieved end-to-end generation at 1.07x playback speed through architectural optimizations and precise engineering. This technical deep dive explores the optimizations and practical lessons for startups building ultra-low-latency generative AI on Google Cloud. Live world models are fundamentally different from standard batch inference due to a batch size of one and strict sequential dependencies. Visko's pipeline chains three generative models on one Cloud TPU slice, sharing hardware for each chunk.