Google Cloud Blog
Follow
Networking for AI inference model serving - GKE only and for all other backends
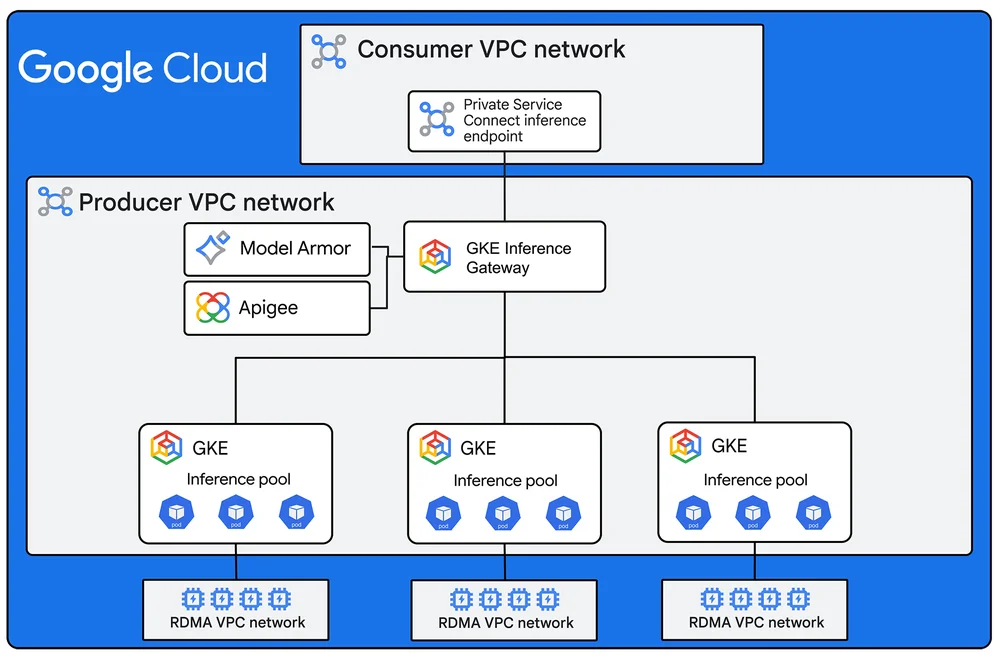
Enterprises often run multiple AI inference models, necessitating architectures for simplified calling and centralized governance. Two reference architectures are presented for networking AI inference model serving: one for Google Kubernetes Engine (GKE) and one for all other backend types. Both architectures share common services designed to enhance security and efficiency. The entry point, whether a Cloud Load balancer or an Inference Gateway, provides a stable and secure frontend for inference calls. This entry point handles TLS termination, integrates with API management, and can extend functionality with service extensions.Common services across both designs include a Private Service Connect inference endpoint to anchor the entry point within a consumer VPC network. Apigee API Management is an optional service for client identity verification, rate limits, and quota enforcement. Model Armor functions as an inline AI safety checkpoint, screening prompts and outputs. The GKE-specific design utilizes a GKE Inference Gateway, acting as a specialized ingress engine. This gateway directs queries to appropriate model-serving targets based on HTTPRoute rules.Inference pools, logical groupings of model replicas, are used, with the Gateway selecting the correct pool based on the model identifier. Model replica sets represent uniform groups of individual model replicas deployed across various node pools. For architectures serving multiple backend types, a regional internal Application Load Balancer acts as the central routing proxy. An Inference Payload Processor, implemented as a Service Extension, inspects incoming request payloads to extract the target model identifier. Network Endpoint Groups (NEGs) provide flexible routing to heterogeneous backends based on this identifier.