Google Cloud Blog
Follow
Querying Databricks Apache Iceberg Tables with the borderless Lakehouse
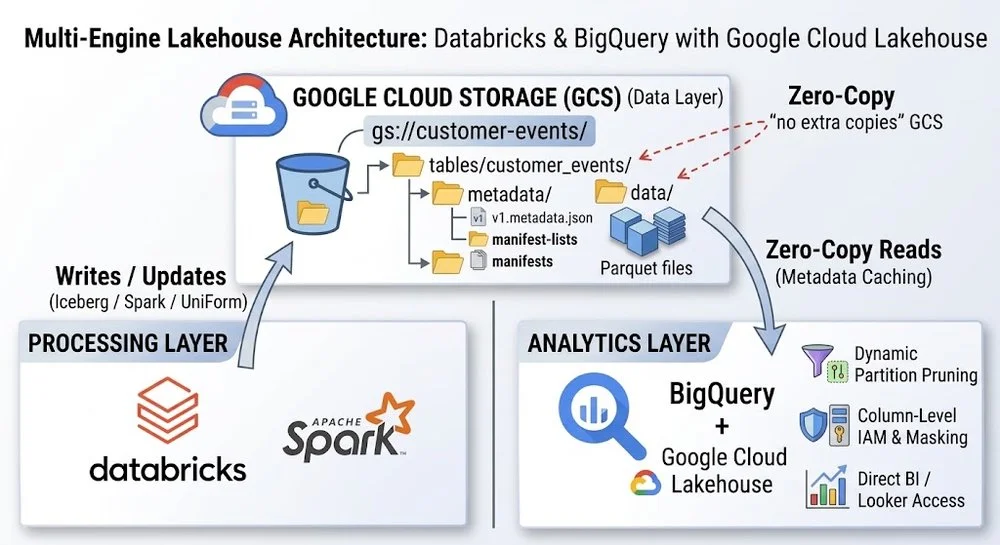
Enterprises can now query Databricks-managed Apache Iceberg tables directly from BigQuery using Google Cloud's Lakehouse. This eliminates the need for complex data copying pipelines, reducing costs and latency. Databricks stores Parquet files in Google Cloud Storage, and Lakehouse reads the associated Iceberg metadata directly. This borderless approach extends to other cloud providers like AWS and Azure, allowing BigQuery to access data without replication. Lakehouse also enables read and write interoperability, allowing multi-statement SQL commands in BigQuery. Security is centralized through delegated access and BigQuery controls applied to external Iceberg tables. Catalog federation and credential vending simplify connections by using Databricks Unity Catalog for metadata. BigQuery uses Iceberg metadata for efficient query planning, reading only relevant data files through partition pruning. Lakehouse caching further accelerates queries for cross-cloud data by storing retrieved blocks locally. Regular maintenance, including compaction and vacuuming, is crucial for optimal performance and cost management. Compaction merges small files into larger ones, while vacuuming purges unreferenced data files. This integration allows for scalable engineering workloads and concurrent analytics without data migration, paving the way for modern AI workloads.