Google Cloud Blog
Follow
Scale your AI workloads faster and more efficiently with GKE Pod snapshots
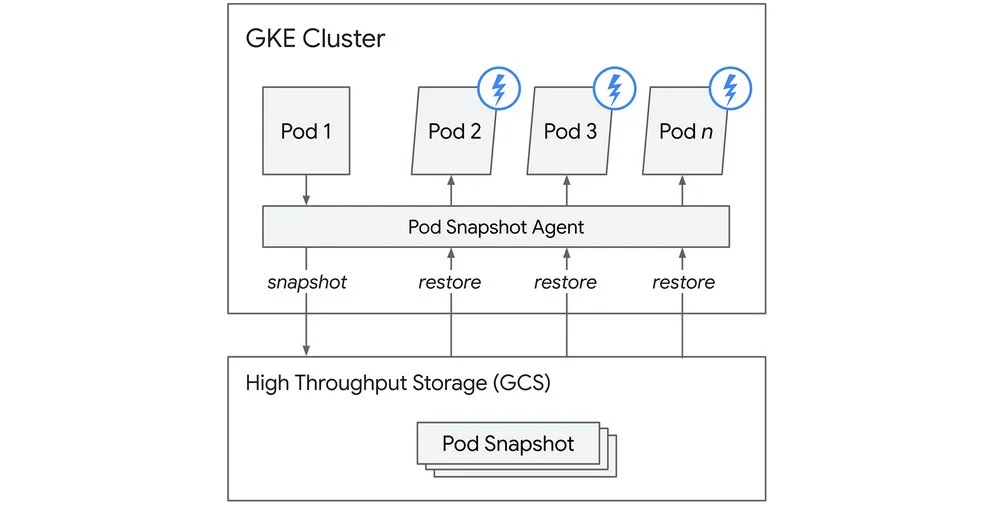
Modern AI workloads face a performance and cost dilemma due to lengthy initialization times. Large language models and instant code execution require fast provisioning, often leading to infrastructure overspending. Google Kubernetes Engine (GKE) Pod snapshots offer a solution by saving and restoring running workload states. This feature drastically reduces AI inference startup times, loading large models in seconds. Cold starts, a problem for many applications, are particularly acute in AI due to significant GPU memory loading. Traditional methods involve overprovisioning or complex custom solutions for state restoration. GKE Pod snapshots enable efficient scaling of AI inference by eliminating redundant model loading for new replicas. A single initialization creates a persistent snapshot, allowing new instances to restore instantly. This accelerates scaling and reduces the need for expensive overprovisioning. For agentic workflows, Pod snapshots improve startup latency and manage idle sandboxes effectively. Snapshots quickly initialize new agent environments and allow idle sandboxes to suspend and resume instantly. This feature is adaptable for various workloads with long initialization phases. GKE Pod snapshots integrate seamlessly with Kubernetes workflows through declarative policies for snapshot management.