AWS Machine Learning Blog
Follow
Use prompt caching with open-weight models on Amazon Bedrock
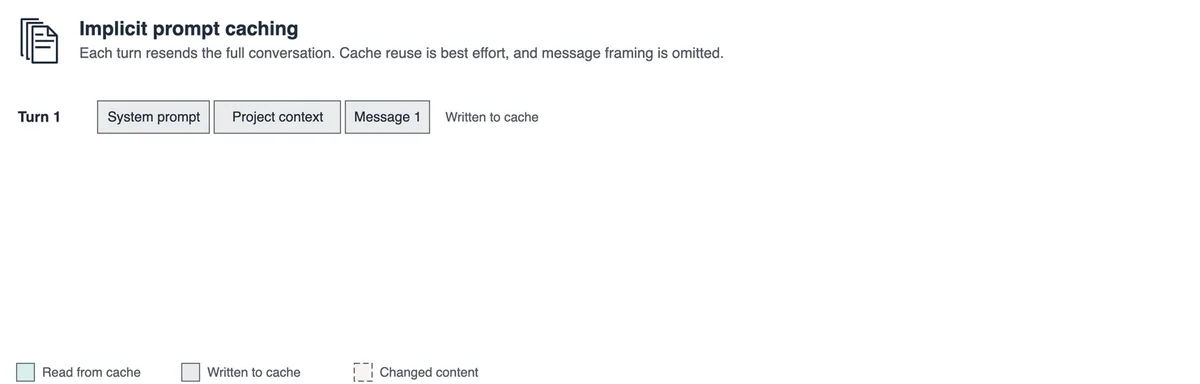
Many generative AI applications resend the same long context on every request. Prompt caching lets open-weight models on Amazon Bedrock reuse it to reduce input cost and latency. This post shows implicit and explicit caching through the Chat Completions API and applies caching to an OpenCode coding agent session.