Google Cloud Blog
Follow
ZenteiQ scales batch inference 4x with GKE Inference Gateway powered by llm-d
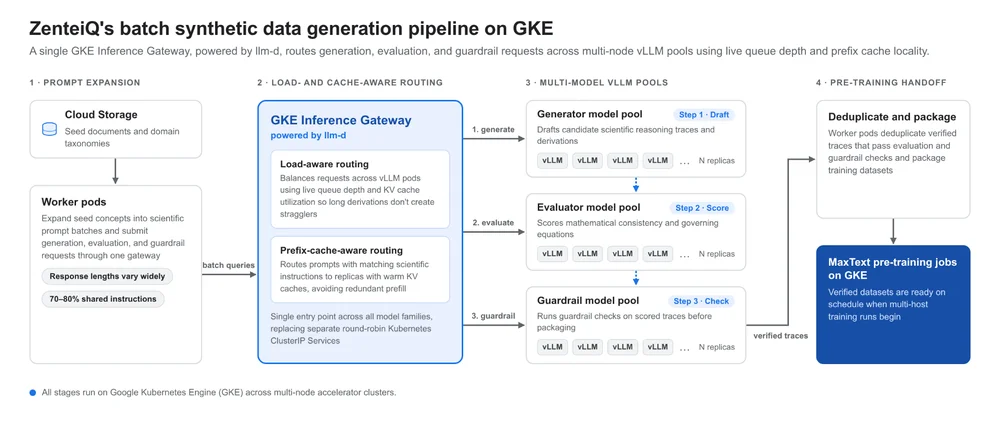
ZenteiQ, an AI startup from the Indian Institute of Science, is building sovereign scientific foundation models. These models require understanding of physics, equations, and numerical solvers, differentiating them from general language models. ZenteiQ employs a large-scale synthetic data generation pipeline to pre-train these models. The pipeline generates billions of reasoning tokens involving complex scientific derivations and solver validation.Previously, ZenteiQ faced routing bottlenecks on Kubernetes, leading to uneven engine queues and redundant computations. This significantly slowed down data generation and delayed pre-training. To overcome these issues, ZenteiQ implemented Google Kubernetes Engine (GKE) Inference Gateway, powered by llm-d. This solution provides intelligent, load- and cache-aware routing for their inference requests.The GKE Inference Gateway monitors real-time queue depths and KV cache utilization across their serving nodes. It routes requests effectively, preventing bottlenecks and reusing cached prompt prefixes. This intelligent routing dramatically increased throughput, with daily output growing from 1.47 billion to nearly 6 billion generated tokens. It also ensured predictability in their pre-training runs. ZenteiQ plans to leverage this setup for future advanced AI training stages.