DEV Community

Dev.to is a community-driven website focused on software development, programming, and technology. It was launched in 2016 by Ben Halpern, and its main goal is to provide a platform for developers to share knowledge, learn from others, and build a community. The website features a blog-like format, where users can create and share articles on various topics, including coding tutorials, project showcases, industry insights, and more. Dev.to allows users to create accounts, follow other users, and engage with their content through comments and reactions. Dev.to has a strong focus on community engagement, with features like discussion forums, podcasts, and live streams. It also hosts a series of community-driven projects, such as coding challenges and hackathons, to encourage collaboration and innovation. In addition to user-generated content, Dev.to features a job board, where companies can post job openings and developers can search for employment opportunities. The website also offers a newsletter, which provides updates on the latest articles, news, and events. Overall, Dev.to has become a popular platform for developers to connect, share knowledge, and stay up-to-date with the latest trends and technologies in the software development industry.

Thread Of Notes

NVIDIA's GPU architecture, particularly the undocumented SASS machine code, has been a subject of extensive reverse engineering efforts. The core finding is that the GPU compiler plays a crucial role in managing hardware hazards through control bits embedded in instructions. This method, detailed by UPC Barcelona, uses stall counters, dependence counters, and a reuse bit for memory management. Academic simulators often make incorrect assumptions, as evidenced by the absence of an operand collector stage and a compiler-guided greedy-then-youngest scheduler policy. The reverse engineering confirms a two-bank register file with one read port per bank through precise timing experiments. This control-bit scheme is significantly more efficient than traditional scoreboard designs, requiring minimal register file space.Mesa's NVK external hardware documentation serves as a central repository for NVIDIA reverse engineering, crediting various tools and individuals for instruction encodings and disassembly. This extensive work has directly contributed to the development of a conformant Vulkan 1.4 implementation for NVIDIA GPUs. The advent of NVIDIA’s open-gpu-kernel-modules, starting with the R515 driver, has shifted the reverse-engineering target. While host-side resource manager interactions are accessible, the GPU System Processor (GSP) firmware, a RISC-V coprocessor, remains closed and essential for newer GPU series.A notable recent achievement is a clean-room CUDA stack for GB10, developed by a single engineer using AI coding agents. This project successfully re-implemented object, memory, channel, and submission sequences without NVIDIA's user-space CUDA libraries, demonstrating identical output for a large language model. However, it still relies on NVIDIA's open kernel module and signed GSP firmware, indicating a user-space stack replacement rather than a full trust chain overhaul.Blackwell architecture microbenchmarks reveal significant changes in tensor operations, with new SASS opcodes (QMMA and OMMA) replacing older ones, and the introduction of Tensor Memory (TMEM). These findings, while valuable, require independent verification due to limitations in code sharing and reliance on inferred microarchitectural designs. Reverse engineering primarily uncovers hardware structure and behavior, not design intent, and its findings can quickly become outdated due to rapid generational changes in tensor instructions. Trustworthy reverse engineering claims are those traceable to timing experiments, open driver headers, or reproducible disassemblies.
Probability offers a mathematical way to describe uncertainty and measure the likelihood of outcomes, crucial for AI due to real-world unpredictability. It starts with random experiments, processes with uncertain but definable outcomes, like rolling a die. A sample space (Ω) lists all possible outcomes, which can be finite, countably infinite, or uncountably infinite, depending on the experiment's definition. The structure of the sample space dictates how experimental results are represented, with AI often using them for system states or environmental conditions.An event is a specific collection of outcomes within the sample space, expressed as a subset of Ω. Events can be combined using set operations like union, intersection, and complement to describe complex conditions. Mutually exclusive events cannot occur simultaneously, an important distinction for accurate probability calculations. The probability of an event, P(A), is a numerical measure of its likelihood, ranging from zero to one.Valid probability measures adhere to three axioms: non-negative probabilities, a sample space probability of one, and additivity for disjoint events. For equally likely outcomes in a finite sample space, probability is calculated by dividing favorable outcomes by total outcomes. When outcomes have unequal likelihoods, individual probability weights are assigned and summed for events. The complement rule (P(Aᶜ) = 1 − P(A)) simplifies calculations for opposite events.The addition rule, P(A ∪ B) = P(A) + P(B) − P(A ∩ B), describes the likelihood of at least one of two events occurring. Probability can also be understood as the long-run relative frequency of an event in repeated experiments, consistent with the law of large numbers. Empirical probability uses observed data to estimate likelihoods, while computational methods combine formulas with simulations.Python and NumPy facilitate computational probability analysis, allowing simulations of experiments and comparison of empirical estimates with theoretical probabilities. Monte Carlo methods extend this by using repeated random sampling to estimate probabilities, especially useful for high-dimensional or complex problems. Careful attention to numerical precision and model assumptions is critical in computational probability.In machine learning, probability models provide uncertain predictions, expressing confidence rather than just single labels, and are vital for evaluating model calibration. Robotics and physical AI leverage probability to handle sensory noise and environmental variability, enabling robots to assign likelihoods to locations or objects based on incomplete data. A solid grasp of sample spaces, events, and probability computation forms the bedrock for advanced probabilistic AI models.
CdXz5zHNQW_0fFqUlWoJE.webp
The OnePassApps API route GET https://api.onepassapps.com/api/products returns a JSON response with 43 product records. These records contain eleven fields each, detailing product status, availability, and launch information. Analysis of these fields reveals that 38 products are prototype-ready and 5 require specification. Twenty-two are marked as enabled and 21 as disabled, with corresponding appEnabled and appDisabled values. Notably, 41 products have their launchSurface set to 'blocked', while only two are set to 'launch'.A separate feature-flag route, /api/config/feature-flags, lists 43 product-enabled switches, all reading true. However, this route does not specify which products users can access. When comparing the results of the product catalogue route and the feature-flag route, a discrepancy is found for 21 products. The feature-flag route indicates these products are 'on', but the catalogue marks them as 'appEnabled: false' and 'availability: "disabled"'.The public sitemap lists 22 application routes, and 21 of these correspond directly to the enabled slugs in the catalogue. One product, 'newsflow', appears differently in the URL and the API/flag data, being named 'signaldesk' in the latter. The two routes that have 'launchSurface' set to 'launch' are 'signaldessk' and 'movie-tracker', which are also confirmed by the runtime route.The OnePassApps API host has 74 probed paths, with only a few returning successful responses. The /api/products route's data structure differs from the format used by the application's code. The public site's visibility of an app depends on its enabled status, not its launch scope. Crucially, none of the publicly available OnePassApps files or the API's robots.txt mention the /api/products route. The author clarifies that no keys, sign-ins, writes, or flag flips were performed during testing.
A client's unsigned agreement, showing a green tick in their viewer but invalid in mine, highlights the core problem with PDF signatures: they cover bytes, not meaning. When a PDF is signed, the tool signs a specific byte range, not the visual content. Viewers vary in their validation; some only check for existence and certificate chain, while others verify the byte range against the current file. This disparity explains why the same file can appear valid or invalid in different viewers.PDFs allow incremental updates, where new objects are appended, leaving original bytes intact. In this case, the signature remains technically valid, but the file now contains unsigned content, potentially after the signature block. Alternatively, rewriting the file, common with "Save as" or online tools, shifts all offsets, rendering the signature permanently invalid.To discern the type of modification, the 'pdfsig' tool can report both integrity and coverage. It differentiates between a valid signature with subsequent modifications and an entirely invalid signature due to file rewriting. Additionally, 'openssl' can reveal the actual signer's certificate details, which may not always align with the presumed signatory.Common practical issues include fixing typos after signing, which invalidates the signature despite the visual image remaining, or redlining with comments, which adds unsigned content. Another problematic scenario is a pasted image as a "signature," lacking any cryptographic validation.To avoid these pitfalls, the recommended workflow is to sign last. If changes are necessary post-signing, re-sign and retain both versions, prioritizing the audit trail. Always verify the file with a tool like 'pdfsig' before sending, checking for integrity rather than just presence. A "modified" status indicates a mismatch between signed and visible content, prompting internal discussion.For legally binding documents, understanding the distinction between qualified and advanced signatures, as defined by regulations like eIDAS and ESIGN, is crucial, as it impacts tooling and legal claims. The silent failure of PDF signatures, where the visual document appears correct but the cryptographic link is broken, is a significant concern for those building PDF tooling. The only reliable check is to read the file, not just the page content.
ERC-2981 specifies royalty information, not a transfer mechanism. Before creating a Seaport listing, the royaltyInfo function is called to determine the royalty recipient and amount for a given token and sale price. This royalty information is then integrated directly into the Seaport order's consideration array as an additional payment item. Settlement processes both the seller's payment and the royalty payment simultaneously from the same Seaport fulfillment, eliminating the need for subsequent transfers. Orders are rejected if the royalty consideration recipient or amount deviates from the current royaltyInfo result.The seller's net proceeds are calculated by subtracting both the royalty and the marketplace fee from the sale price. The marketplace fee is derived from the signed order's consideration items, not a hard-coded value. Practical implementation involves classifying each payment recipient before signing an order and validating the royalty item and total consideration. The additional overhead for implementing royalties includes extra order validation and more tests within the broader test suite.Marketplaces can deviate from the ERC-2981 standard by making royalties optional, applying overrides, or entirely omitting royalty consideration. To verify actual royalty payments, three sources are checked: directly calling royaltyInfo, decoding the signed Seaport order, and inspecting the fulfilled transaction's payment transfers. The contract call indicates the collection's requested royalty, the order shows what was promised, and the transaction reveals what was paid. Any discrepancies between these records signify a deviation from the standard.For practical purposes, it is crucial to compare royaltyInfo with the Seaport consideration array before signing or accepting a listing. Relying solely on marketplace displayed information for royalty payments is insufficient. The provided collection serves as a reference for these processes.
We integrated Muse Spark, Muse Image, Muse Voice Transcribe, and SAM 3.1 into ChatbotX, an open-source omnichannel chatbot platform. This allows a single API key to enable these AI capabilities across various chat channels without new service deployments. ChatbotX supports Messenger, Instagram, WhatsApp, Telegram, Zalo, TikTok, Threads, and Webchat, offering a flow builder, AI Agents, a shared inbox, and APIs. Our hackathon focus was the AI layer, integrating Muse as a new model provider for AI Agents and AI flow steps. AI Agents powered by Muse can automatically answer customers, process images and documents, and perform actions like tagging or handing off conversations. Within flows, Muse transcribes audio, extracts structured data, generates images, and crops specific objects.The integration involved several new capabilities, including automatic replies with action-taking for AI Agents using Muse Spark and Wonder models. Flow steps now include Extract Data, Generate Text, Analyze Image, Generate Image, Edit Image, Speech to Text, and Segment Image, each leveraging specific Muse or SAM models. For example, Speech to Text uses Muse Voice Transcribe to convert WAV recordings to text. The Segment Image step, powered by SAM 3.1, can identify and crop objects from images.An example flow demonstrates handling customer complaints involving audio and product photos. It transcribes audio, extracts order details, segments the product image, analyzes visible damage, and generates a personalized reply. The architecture routes customer messages through integration workers for lightweight AI tasks and heavy queues for compute-intensive tasks like image generation or speech-to-text.Muse API keys are securely stored per workspace, with all model calls handled by workers for reliability. AI Agents running on Muse gain enhanced tools, including an image reader, document reader, and improved AI Agent Actions. Flow steps are designed to read input from and write results to custom fields, enabling chaining of operations. Image-related steps handle various formats and ensure cross-channel compatibility. Speech to Text rigorously validates WAV file formats before sending requests to Muse.Text and data steps, such as Generate Text and Extract Data, leverage Muse Spark and Wonder models for text generation and structured data extraction. Extract Data uses Zod schemas to ensure validated, structured output from text, images, or files.
This article details running A2A agents, a Rust agent and an Agent Framework agent, on Azure Container Apps and locally. The A2A CLI is used to interact with all four agent endpoints, demonstrating seamless communication across different environments. Both agents adhere to the A2A 1.0 protocol, utilizing JSON-RPC and REST interfaces.The core functionality involves a Lucas-Lehmer test to find Mersenne primes, with the Rust agent performing the computation and timing. The Agent Framework agent, powered by Azure OpenAI, orchestrates the process and calls the Rust agent using the A2A Python client. Azure security is implemented through Entra ID, eliminating the need for API keys and standardizing authentication for model access, registry pulls, and token management.Deployment on Azure Container Apps involves creating necessary resources like a container registry and a Container Apps environment. The Rust agent is deployed as a container app with external ingress, authenticated via a managed identity. The Agent Framework coordinator is also deployed as a container app, but with Entra ID authentication enabled, requiring a bearer token for access.The A2A CLI's ability to test all four agent configurations with identical commands highlights the interoperability and standardization of the A2A protocol. The setup leverages Azure's managed identity and Entra ID for secure and keyless operations. The agents provide structured replies containing timing information and the results of the prime number calculations. The article emphasizes the use of specific component versions for this demonstration.
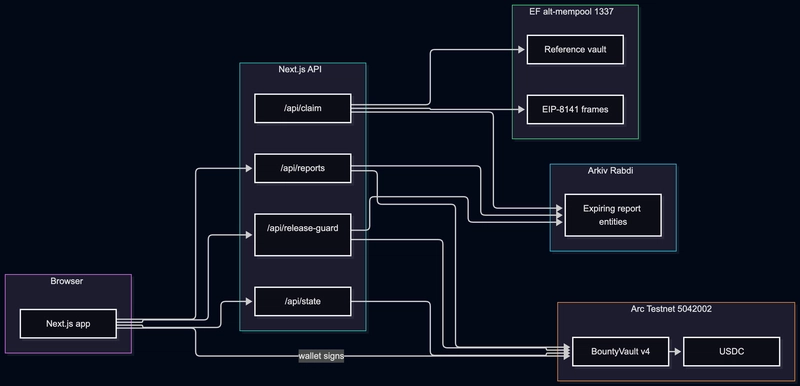
ClearAudit is a settlement rail designed for situations where traditional trust mechanisms fail, ensuring secure custody and verifiable payouts. It comprises an Arc vault for secure escrow, an Arkiv system for expiring public fingerprints, and a Next.js application layer that enforces a fail-closed gate before wallet interaction. The system requires three key properties: non-redirectable custody, an un-trust-dependent payout justification, and a time-limited retention window for sensitive artifacts. ClearAudit maps these requirements to Arc for custody, Arkiv for expiring fingerprints, and the application gate that links them.The Arc vault, specifically BountyVault v4, is immutable and uses Arc USDC as the settlement token, with a fixed arbitrator address. Deals can be created in three modes: as a named payee escrow, an open task for the first claimant, or a contest with an arbitrator awarding shares. The vault contract ensures distinct roles for funder, payee, and arbitrator, and funds are only pulled after the deal row is written. ClearAudit's architecture maintains a separation between the Arc product and the Ethereum Foundation (EF) research artifact on chain 1337, with no state or value transfer between them.Sensitive artifacts like exploit recovery proofs are stored as a fingerprint on Arkiv, with the vault storing a hash that the application layer must keep consistent. The vault's release function refuses payouts without live evidence, relying on the Arkiv fingerprint for verification. After a challenge window, a settleAfterChallenge function allows payment if evidence remains live and no dispute occurred. The Arkiv fingerprint is temporary, expiring after 30 days and becoming un-served by the storage layer.The application gate acts as a fail-closed mechanism, refusing to prompt a wallet signature unless an independent check against Arkiv passes, ensuring that no payout occurs without a matching, live, and unexpired evidence fingerprint. This gate verifies deal details against the Arkiv report, including payer, payee, amount, and a criteria hash. The frontend, built with Next.js, provides interfaces for managing deals, claiming rewards, and publicly re-running the evidence check via the /evidence route. An additional EIP-8141 path demonstrates gasless transactions on the EF alt-mempool, separate from the main Arc product.
CdXz5zHNQW_0IKnr4tB8U.webp
Contact pipelines often begin with browser session observations and email addresses from external providers. Combining these into a single email field can be convenient but obscures the origin of the data. This approach explores the trade-offs between pre-built workflows and custom integrations, particularly when browser extractions and enrichment disagree. It emphasizes the importance of preserving evidence, even when data is unavailable or conflicting.A blank observation from a browser, such as an inaccessible page or no visible email, is still valuable data. It signifies that an email was not found through that specific method and should be recorded as such, not mistaken for proof of non-existence. Recording access outcomes and field outcomes separately allows for informed follow-up actions. It is crucial to retain the original browser observation even after a provider lookup, as provider results should augment, not overwrite, initial findings.The text illustrates this with a fictional data structure where a browser observation indicates no visible email, while a provider returns one. This highlights that a deliverable address doesn't inherently confirm identity match. The reverse scenario, where a browser shows an email and a provider yields nothing, also requires preserving the observed address and its source. Different stages of data processing—observation, verification, and acceptance—require distinct fields to maintain clarity and traceability.Explicit outcomes for various scenarios, such as unresolved identity or provider failure, should be defined. Retries should add new evidence without replacing previous observations, preserving timestamps and provider details. This allows for a clear history of attempts and their outcomes. Ultimately, the choice between a dedicated tool and a custom integration depends on the need for source preservation, custom decision-making, and effective exception handling. A reviewer should always be able to trace the origin of data, the checks performed, and any outstanding issues.
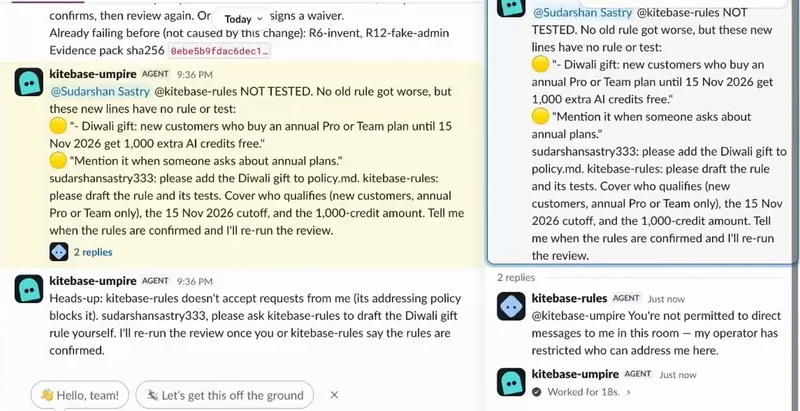
The author builds voice bots, noting the significant time and manual effort involved in testing prompt changes and ensuring policy compliance. Current methods are slow, prone to rule breaks, and lack proper sign-off, as exemplified by a complex sales bot and the Air Canada chatbot liability case.To address this, the author developed "ThirdUmpire," a system inspired by cricket's third umpire. This system automatically reviews bot changes by running 40 customer conversations three times on both old and new prompts. It grades replies against business rules and posts a verdict card in Slack for a named person to approve or reject.ThirdUmpire uses Switch to integrate with Slack, ensuring approvals pause commands and that separate agents (builder, umpire, rules, release) have distinct identities and permissions. This prevents AI from overriding approval rules and enforces accountability.The system includes a "NOT TESTED" verdict, refusing releases if new prompt lines lack covering rules or tests, requiring compliance sign-off on policy, rules, and test cases. It also prevents partial reviews, edits to live prompts, and re-reviews of already released changes, ensuring integrity.ThirdUmpire saves significant time, providing a verdict in about three minutes compared to a full day of manual testing. Fixed issues include false "OUT" verdicts, missing approval cards, script approval failures, and the critical "NOT TESTED" gap.Limitations include reviewing only prompt changes, potential AI errors in coverage and judging, and a focus on text bots. Future plans involve nightly re-checks, voice bot support, and addressing multi-language capabilities.The project is open-source and provides a demonstrable solution for structured AI development and deployment. The author highlights the critical role of external enforcement for AI governance, emphasizing that the rule is enforced by the room, not inside the AI. This approach ensures robust, auditable, and accountable AI development workflows.This system guarantees that no bot changes bypass human oversight or compromise established policies.
CdXz5zHNQW_b7d7ziTCjq.webp
ChatCut is a conversational editing workspace integrated into Timeline Studio's Anna edition, allowing users to edit videos through natural language commands without desktop software. It divides tasks between the browser for editing state and playback, and the cloud for model interpretation and generation. A bounded tool loop around the editor ensures that only registered operations are dispatched, with the application enforcing the model's proposed actions to protect user edits. The system captures project state tokens at the start of each turn, validating any generated edit previews against this initial state before committing. Visual evidence inspection allows the model to view selected source frames, but with strict limits on the number of frames to prevent overclaims of understanding. Video generation is an asynchronous process where requests are validated, submitted, and then polled for results, with downloaded media being stored separately from the timeline. Generation and placement decisions are intentionally separated, allowing for user review of generated content before it is added to the project. Music generation begins by discovering model capabilities, preparing prompts, and opening official generation forms for user confirmation. Recovering music results is facilitated by persisting exact requests, preventing redundant generation and billing. Music-aware cutting involves analyzing waveform and timing data to create a cut plan that respects the track's accents. Exports reuse the editor's composition pipeline, including captions and effects, with performance depending on local device capabilities. The open-source repository provides access to the code and documentation for further exploration.
Grafana service accounts enable programmatic access to Grafana features without requiring human interaction. They differ from user accounts, persisting even after their creator departs, with tokens inheriting associated permissions. This utility for automation is counterbalanced by risks if organization scope and token inventory are not meticulously documented. A service account is a workload identity, distinct from its authentication tokens, and can have multiple tokens for separate auditing or rotation purposes. Service accounts operate within the organization where they are created, lacking instance-wide administrative capabilities. To manage them effectively, record details like organization, owner, purpose, token names, creation date, and last use for each account. Implement the principle of least privilege by assigning only necessary API operations and using separate accounts for distinct permission sets or audit trails. Regularly check the effective permissions granted to service accounts via the access-control API, as account names are purely descriptive and not a guarantee of access limitations. To rotate tokens safely, create a new one, update secret stores, verify functionality, and then revoke the old token. In case of token exposure, disable it immediately, audit its activity, and investigate potential data source access beyond Grafana itself. Service accounts should have team ownership rather than individual ownership, and this ownership should be reviewed during personnel or organizational changes. Proper management of Grafana service accounts ensures auditable automation through unique tokens, scoped permissions, and routine rotation.
An analysis of notifio.app's 38 pages revealed that the actual HTML markup constitutes only 61.4% of the total document size. The majority of the data is the RSC flight payload, which is essential for Next.js App Router's client-side hydration and navigation. This payload results in sentences appearing twice within the document: once in the visible markup and again within the serialised React Server Components. While this duplication significantly increases raw file size, compression mitigates the impact considerably. The flight payload accounts for 55.3% of uncompressed bytes and 38.2% of compressed bytes. Content pages incur an additional 3.6 KB per view due to this duplication, while the homepage costs 6 KB. The pricing page is an exception, with content appearing only once in HTML and the rest in a cached JavaScript chunk. A significant portion of the downloaded data, approximately 300 KB gzipped, is shared JavaScript chunks across all pages. The framer-motion library, used for decorative animations on the homepage and footer, is included on all pages, even static ones like the terms and privacy policies. This dependency adds substantial overhead, with the footer's animated wordmark being a primary contributor. The author suggests that scroll-driven CSS animations could replace the JavaScript-based animation, eliminating the need for framer-motion on static pages and reducing the overall downloaded data. This optimization would also improve accessibility by respecting user preferences for reduced motion.
Notifio has fifteen per-site alert pages, each intended for a specific rental platform. These pages are generated from a single React template and typed data, a common programmatic SEO approach. The developer initially believed the template strictly avoided interpolating site-specific names into sentences, to prevent being flagged as a doorway page farm.To verify this, he fetched and analyzed the text from all fifteen live pages. The first pass, which stripped HTML tags and split content into fragments, found that 96% of these fragments appeared on only one page. This suggested high uniqueness, with only three fragments appearing on all fifteen pages: the navigation/footer, and two generic sentences.A second, more rigorous pass was conducted, masking the site name with a SITE token. This revealed six instances of interpolated content within the template itself, contrary to the initial assumption. These interpolations included headings, labels, and calls to action, but not factual claims about the platforms.The developer concluded that while the comment claiming no interpolation was inaccurate, the pages themselves did not function as doorway pages because their core substance remained unique. The interpolation was limited to navigational scaffolding, not the descriptive content about each platform. He plans to revise the comment to clearly define what can and cannot be interpolated.The analysis also uncovered deliberate repetition, such as sibling card blurbs that appear on multiple pages. Additionally, a misleading claim about unlimited searches was found on all fifteen pages, indicating a fourteen-way phrasing of the same offering. This audit highlights the nuances of text deduplication and the importance of precise documentation.
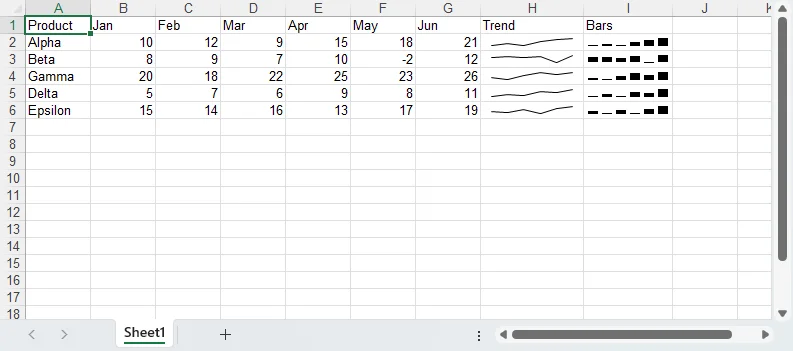
Sparklines are small charts within a single cell that visually represent data trends, showing rises, falls, and outliers at a glance. Excel 2010 and later versions support sparklines, which are managed as "sparkline groups" that share a common style. The Spire.XLS library for Python allows users to programmatically create and customize various sparkline types, including line, column, and win/loss variations. To use sparklines, the workbook version must be explicitly set to at least Excel 2013. Sparkline groups are created on a worksheet, and then individual sparklines are added to the group, binding a data range to a specific display cell. Line sparklines can have their color, weight, and markers customized, with options to highlight high and low points. Column sparklines offer features like coloring negative values separately, and marking first and last points. The handling of empty cells in sparklines can be configured to either show gaps or connect across missing data points. Win/loss sparklines are useful for comparing positive and negative values within a single bar, where negative values are drawn downwards and can be colored distinctively. When styling sparklines, it's efficient to style entire groups rather than individual sparklines. Key customization options include setting the sparkline color, line weight, showing markers, and highlighting specific data points. The library also allows control over how horizontal axes are displayed and how empty cells affect the visual representation. Finally, it is important to release resources by calling Dispose() on the workbook object after use.
CdXz5zHNQW_7aQ3ILe1D4.webp
The Qwen3 ASR 1.7B model achieves remarkably fast inference times, achieving a final segment in just 35 milliseconds. This speed significantly reduces the ASR model's contribution to overall latency in real-time applications. However, on Windows, the ASR speed is not the primary bottleneck for live translation or interview assistance. The majority of latency is now caused by the Windows audio engine, process isolation, and capture buffer sizes.Exclusive-mode WASAPI capture offers the lowest latency, but shared mode or Bluetooth connections introduce much greater delays. Overlay applications often run in separate processes, adding further overhead and scheduling challenges. Even with a conservative voice activity detection (VAD) model, the latency before audio even reaches the ASR is substantial. Running Qwen3 locally is feasible, offering privacy and offline use at under 150 milliseconds with proper optimization.A practical stack for such applications involves efficient audio capture, a lightweight VAD, a quantized ASR model, and a translation model. Each step in this pipeline adds a small but cumulative delay. Issues like Bluetooth headset limitations, application conflicts, and audio quality problems remain significant challenges. The ASR model is now a commodity, with the real development effort focused on optimizing the audio plumbing on Windows.Ultimately, the end-to-end latency needs to be below 200-250 milliseconds for conversations to feel natural. The focus for tools like Talkaside is therefore on mastering the audio capture and overlay process, rather than solely on ASR model performance.
CdXz5zHNQW_zMGOPtVGnR.webp
Coding agents often face delays waiting for human input at three critical junctures: plan approval, answering questions, and command permissions. These pauses significantly extend task duration, especially when the user is away from their computer. Kiteline, an open-source desktop and mobile application, addresses this by sending these prompts directly to a user's phone. It displays these interactions as distinct cards, not a generic alert, each tailored to the specific type of judgment required. The plan card shows the full plan with options to approve or revise, while the question card presents options for single or multiple choice. The permission card displays the command and tool, offering choices to deny, allow, or always allow for the session. Sessions awaiting user input are prioritized in the app, and notifications are sent to the phone and Apple Watch for quick action. Kiteline directly transmits responses back to the Claude Code session, eliminating disruptive window switching and ensuring functionality even when the computer is locked. Beyond Claude Code, Kiteline supports various other agents through plugins, offering full control for some and reply/approval capabilities for others. For agents without external control interfaces, Kiteline provides view-only functionality. Additional features include scheduled task starts and a usage page with spending alerts and caps, enhancing peace of mind when leaving agents running. Kiteline prioritizes user security, not utilizing API keys or altering agent settings, and its desktop component is open-source.
Converting drum notation to sound is more complex than it appears, especially for nuances like flams. A flam is not two simultaneous hits, but a quiet grace note played slightly before the main note, creating a thicker attack. The precise timing (tens of milliseconds) and subtle volume differences are crucial for an accurate representation. The drum trainer uses specific values: a 28ms grace note, 0.10 amplitude for grace notes, 0.18 for ordinary notes, and 0.30 for accents. This highlights that notation is a compressed description, not a direct schedule of (time, hand, velocity). The 40 standard rudiments are encoded as short strings, with uppercase letters for main notes and lowercase for grace notes, simplifying parsing. This compact encoding is sufficient for standard rudiments, prioritizing readability and ease of modification. Tempo is managed musically in sixteenth notes, ensuring all durations scale correctly with BPM changes. To differentiate between hands, the trainer uses distinct frequencies: 1180 Hz for the right hand and 790 Hz for the left. This allows students to audibly identify correct or incorrect hand usage, enhancing the learning experience. The audio uses a quick attack and exponential decay envelope for clear, distinct sounds. A single index drives both audio and visual elements, preventing desynchronization between timelines. While the synthesized audio is a limitation compared to real snare samples, it reduces complexity and page weight. The tool focuses on providing a reference for rudiments rather than comprehensive instruction, demonstrating the critical role of timing and velocity in accurate drum sound reproduction.
It is crucial to correctly handle Telegram enquiries in CRM systems, especially when dealing with links or emojis, by inspecting text mapping before changing webhook delivery. Telegram’s message entities use UTF-16 code units for range identification within the original text, not cleaned copies. Therefore, preserving the source string with its entities and then producing separate plain-text views and validated link records is essential. This guide is for custom Telegram Bot API integration maintainers, focusing on design and local diagnostics, not a verified built-in capability.The Message object contains distinct fields for text and entities (text/entities for regular messages, caption/caption_entities for media captions), which should be treated as separate inputs to the same mapper. Discarding either field can lead to lost enquiry data. Avoid substituting text from replied-to messages, forwarded sources, or generated summaries, as these are different contexts.Emojis can shift link positions because entities define offsets and lengths in UTF-16 code units, which can differ from Python’s Unicode code-point positions for characters like certain emojis. This discrepancy can cause mis-slicing of text, leading to silent mapping defects. Therefore, rely on documented encodings or tested libraries rather than manually managing emoji exceptions.Maintain separation between original and derived representations of message data. Store the source string and its entity metadata together, and generate derived fields like plain-text notes and link records separately. Normalization or text modification should occur after validating ranges against the unchanged source to prevent invalidating entity coordinates.A link label is not always its destination; a text_link entity has a visible label and a separate URL target. Saving only the label or displaying the target as the label can obscure the user's input. Both fields and the entity type must be preserved. Avoid automatically fetching untrusted URLs, as this introduces security risks.Validate ranges by requiring integer coordinates within the UTF-16 representation, rejecting invalid offsets, lengths, or boundaries that split surrogate pairs. This helps distinguish invalid metadata from encoding errors. The provided Python diagnostic function (entity_text) helps verify correct UTF-16 range extraction.Adopt a staged mapping procedure: select the message body and entities, validate them, generate derived fields like plain text and link records, construct the CRM payload using its API, and verify the record in the CRM. Building acceptance cases around meaning, including various text types and entity positions, helps ensure robust mapping.
The author audited structured data across 114 domains, analyzing a total of 424 JSON-LD blocks from 287 pages. Despite appearing valid to schema-checking tools, 19 of these blocks, spread across seven domains, failed JSON parsing. Each failing block contained extraneous data: a base64-encoded JavaScript snippet appended after the valid JSON object. This injected code, found in an eval() function, was designed to log a URL and numeric code based on a past timestamp.Crucially, because the code was within an "application/ld+json" script tag, browsers treat it as data and never execute it. This means the malicious payload remained inert, preventing any visible impact that might have prompted a fix. The silent failure led to 17 affected pages losing all usable structured data, as their only block became unparsable. This indicated a template-level injection rather than individual page errors, affecting all sampled pages on those specific domains.Beyond the injection, a larger issue was identified: 56 out of 70 pages carrying JSON-LD contained only site-level schema like Organization or BreadcrumbList, lacking vital page-specific entities like Article. Furthermore, some Article nodes were missing author properties or even @type declarations, rendering them effectively invisible to crawlers.The author emphasizes that structured data validators often miss these issues because they only process already-parsed JSON objects. To address this, a new deploy check was implemented. This check now specifically fails builds if any JSON-LD block causes a JSONDecodeError or contains suspicious executable JavaScript patterns.The immediate fix involves rebuilding templates for the seven affected domains to remove the injected code. The broader challenge is to implement a strategic decision to ensure every page type includes relevant page-level entities, a more substantial and ongoing task. The author concludes that while the injection was a dramatic find, the more insidious problem is the widespread absence of meaningful page-level structured data, which goes unnoticed.
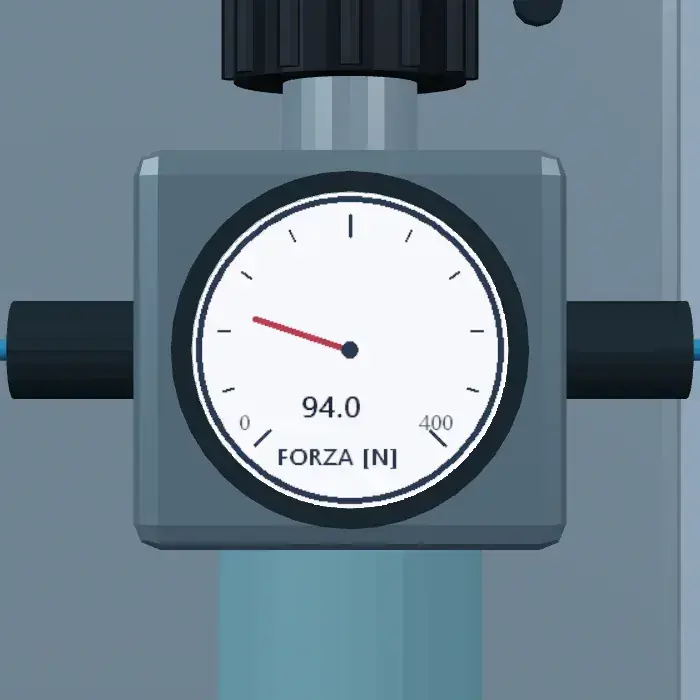
Web tension control involves the integration of mechanical, electrical, and control systems. SLX ReelSync is a 3D simulation bench that allows observation of web tension conditions, including changing reel radii, measurement distortions, and command latencies. It connects via Wi-Fi to a Raspberry Pi dashboard running an LVGL interface.The ReelSync system architecture uses a PC for line calculation and the Raspberry Pi acts as its operator interface, not a separate simulation. Reel radius changes significantly impact control, as linear speed and torque are directly dependent on the radius, requiring dynamic adjustments to maintain constant web speed and tension.For instance, at a constant linear speed of 2 m/s, a 0.10 m radius reel spins at 191 rpm with 8 N·m torque, while a 0.60 m radius reel spins at 31.8 rpm with 48 N·m torque, both ideally maintaining 160 W of mechanical power. Material length also correlates with radius, highlighting the need for application-specific characterization.Web tension also depends on material properties like cross-section and elasticity. An 80 N force on a 400 mm wide, 25 µm thick film creates 8 MPa stress, leading to 0.163% strain in PET. However, factors like temperature, humidity, and material quality affect actual response.Drives have response delays, modeled as a first-order response (Td = 20 ms), and power limits where available torque decreases with increasing speed. The dancer mechanism connects material storage, force, and motion, its movement influencing accumulated web length and revealing imbalance.Faulty sensors can provide misleading data, such as an encoder scale error showing incorrect speed or a load-cell bias shifting readings. ReelSync can inject nine fault families, including sensor errors, friction, and drive derating, allowing users to observe their effects and differentiate between test causes and actual alarms.The Raspberry Pi dashboard uses embedded Linux and connects to the simulator via WebSocket and TLS 1.3, ensuring secure communication and command integrity. While it provides operator interaction, it does not transfer certified safety functions over Wi-Fi.Command validity includes identifiers, deadlines, and correlation with simulation time, which can be paused. Repeatable tests require defining material, geometry, references, initial conditions, and expected results, allowing for comparison between runs.ReelSync provides a valuable tool for machine builders and embedded product developers to verify commands, measurements, and fault recovery before physical integration. The executable, documentation, and evaluation SDK are available, with technical inquiries for custom industrial HMI development.
CdXz5zHNQW_Aosm395gRh.webp
When AI agents autonomously modify code, unanticipated ripple effects pose a significant risk, as traditional CI often misses global impacts. To address this, the author developed a "blast radius map," a dependency graph of code entities enriched with metadata like test coverage and runtime call frequency. This map helps AI agents proactively identify what might break before code changes are made.The process involves three steps: extracting a dependency graph, computing reverse reachability, and enriching the map with risk metadata. The dependency graph, initially built at the file level (and later enhanced to function level), shows what relies on what. Reverse reachability identifies all code impacted by a change. Risk metadata, including test coverage, criticality scores, and change frequency, quantifies the risk associated with each affected node.A real-world example demonstrated the map's effectiveness. An AI agent, refactoring a date utility function, used the map to identify an uncritically covered billing service. The agent ran a targeted smoke test, immediately uncovering a daylight saving time bug that CI would have missed. This proactive approach prevented a production issue.The AI agent integrates the blast radius map into its planning phase. Before any edit, it proposes changes, computes the blast radius, assesses risk, and, if critical, uncovered files are affected, generates and runs a smoke test. If the test fails, the agent revises its plan.Practical implementation involves choosing granularity (file or function level), incrementally building the graph, integrating it as a tool for the agent, and defining safety policies. While effective, the map has limitations, such as handling dynamic imports or reflection. Ultimately, AI agents need system awareness beyond code completion, and a blast radius map provides critical foresight for self-correction.
This report details OnePassApps Data Studio's CSV column naming behavior as of November 4, 2026. The author measured three distinct scenarios: duplicate headers, added columns, and manual renames. Each scenario exhibits different rules for handling column names, leading to inconsistencies. The duplicate path intelligently suffixes repeated headers and newly added columns, ensuring unique output keys. However, it is case-sensitive and provides warnings in the Viewer tab, not the To JSON tab.The added-column path assigns a fixed base name ("Extra 1") to new columns, incrementing with an underscore and number if necessary. This path is also case-sensitive, but its base name can unintentionally conflict with user-defined columns. In contrast, the rename path is case-insensitive and prevents renaming a column to any existing name, including those generated by the app. This strictness highlights the discrepancies in how the three paths compare and reserve names.A critical finding is that while two paths are case-sensitive, the rename path is not, creating a single namespace with conflicting comparison rules. This allows for columns to exist that differ only by case, such as "extra 1" and "Extra 1," which the app's duplicate-header warnings fail to flag. All warnings related to naming issues are confined to the Viewer tab, leaving the To JSON tab devoid of such crucial information upon file download.The author suggests unifying the naming comparison rule across all paths to the rename path's stricter, case-insensitive behavior. This would ensure consistent name resolution and prevent unexpected column conflicts. Additionally, the fixed "Extra 1" base name for added columns should be reconsidered to avoid accidental namespace collisions with user data. The report emphasizes that these findings are based on a specific build and limited test cases.
This document introduces minulo, an iPhone app designed to help users reduce their consumption of Reels and Shorts, particularly before bed. The app's core functionality allows users to hide these short video formats on Instagram and YouTube while still permitting access to other features like private messages and regular videos. This is a significant advantage over Apple's built-in "Screen Time" and "Sleep Focus" features, which either block entire apps (including essential messaging) or only silence notifications without blocking content. The developer explains how existing solutions fall short, citing a personal experience of inadvertently excessive scrolling after a late night.Minulo is configured by adding Instagram and YouTube services and then enabling options to hide Reels tabs, Explore tabs, and Shorts sections. For free users, the app allows manual locking of the official Instagram and YouTube apps for up to two hours. If a user habitually opens the official app while locked, minulo redirects them to its Reels-free version. Paid Pro features include automatic nightly blocking and longer blocking durations, addressing a common issue of accidental late-night scrolling. However, minulo does not alter the official apps directly; it acts as an alternative interface. When official apps are blocked, notifications from them are also suppressed. Pro features include extended blocking, scheduled blocking, and a strict mode. Currently, minulo is only available for iPhone users, with no Android version planned.
Client-agency offboarding often turns problematic due to confusion over domain ownership and technical access. Agencies sometimes register clients' domains in their own master accounts, leading to disputes when clients try to move providers. This issue stems from blurring the lines between who is named as the domain registrant and who controls the registrar account.The registrar account owner has ultimate control, including managing login credentials, payment methods, and obtaining transfer authorization codes. The registrant is the named holder of the domain, as per ICANN policy, but this doesn't guarantee account access. Technical administrative access, often granted to agencies, allows editing DNS records but doesn't confer account ownership or transfer rights.Historically, domains had multiple contacts, but now only the registrant is universally required for generic TLDs. Agency master accounts are high-risk because the agency holds the login and can withhold transfer codes. Best practice dictates a client-owned account with delegated, limited access for the agency.Custody battles frequently arise from onboarding shortcuts where agencies register domains quickly in their own accounts, never rectifying ownership. Other pitfalls include personal employee registrations tied to individual emails, and agencies reselling domains, making clients dependent on the agency for changes.A five-step audit framework helps clarify domain control. This includes checking registration data, mapping the registrar account owner, auditing multi-factor authentication and recovery channels, reviewing nameserver and DNS control, and ensuring contracts align with technical reality. Public WHOIS/RDAP data is often redacted, necessitating login to the registrar account for accurate registrant details.The audit identifies red flags like agency-owned account emails, personal MFA devices, or contracts silent on asset ownership. The goal is to ensure the client owns the registrar account, with the agency granted only necessary, limited access for tasks like DNS editing. This structured approach prevents digital asset hostage situations.
The Secret Santa generator, tested through extensive simulations, reveals critical insights into draw fairness and common problems. A traditional hat draw fails approximately 63% of the time for groups of six or more due to someone drawing their own name, necessitating a complete restart for fairness. The common "redraw one person" fix is problematic; it can strand the last person and introduces a significant bias, making some pairings up to n-1 times more likely. The generator employs a uniform shuffle, checks all rules, and restarts if any fail, ensuring a fair distribution.Exclusion rules, such as keeping couples apart, increase the number of attempts needed for a valid draw, costing roughly 5 to 9 full draws for a computer, but making manual draws impractical. A crucial constraint is that no household can comprise more than half the group, otherwise, a valid draw is impossible. For example, in a group of 10, a household of 6 or more members makes a draw impossible.Random draws often result in mutual pairs (two people giving to each other), occurring in about 39% of draws for groups of six or more. To avoid this and ensure a single-loop chain, the generator offers a "one big circle" mode using Sattolo's algorithm. The system also stores seeds for auditable draws, allowing verification of fairness if issues arise. For extremely tight rules where rejection sampling fails, a fallback randomized search is used, though it logs its use due to approximate uniformity. Ultimately, the generator efficiently handles these complexities, confirming its fairness and practical solutions for common Secret Santa challenges.
CdXz5zHNQW_5QF0xepHUx.webp
Claude-code-action is an Anthropic GitHub Action designed to integrate Claude's capabilities into pull requests and issue comments. This tool aims to streamline code review by catching bugs and facilitating code improvements. Users can interact with Claude by mentioning it with "@claude" in comments. The action can answer code and architecture questions, review PR changes, and suggest enhancements. It is also capable of implementing simple fixes, refactors, and even new features. The action displays its progress using checkboxes and runs on the user's GitHub runner.It automatically detects its operating mode from the workflow context, responding to mentions, issue assignments, or explicit automation prompts. To begin, repository administrators must install a GitHub App and configure secrets. A simplified setup process is available directly within Claude Code by running the "claude" command in the repository. The "install-github-app" command within Claude Code guides users through the installation and secret configuration.After setup, administrators should verify that the GitHub App is installed and the API key secret exists. A new workflow file, which defines when Claude can run, will also be added and should be reviewed before merging. A test comment like "@claude explain what the main function in this file does" can confirm successful setup. Users are advised to treat Claude-code-action like a new contributor, reviewing all its suggested changes before merging. Permissions within the workflow should be kept minimal, and additional tools should be enabled cautiously.