Planet Python

The website Planet Python is a planet site that aggregates Python-related content from various sources, including blogs, news sites, and other online publications. The website provides a one-stop destination for individuals to stay up-to-date with the latest developments in the Python programming world. The content on the site includes tutorials, news, project announcements, and discussions about various Python-related topics. Users can visit the site to stay informed about the Python community, new releases, conferences, and best practices in using the Python programming language. The website's purpose is to help promote and disseminate Python-related content, thereby contributing to the growth and development of the Python community.

Thread Of Notes

There's a significant gap between learning basic Python syntax and building a functional application. Many Python courses focus on language fundamentals but neglect the essential development workflows needed for real-world projects. This often leaves learners confused about topics like installing Python, using the terminal, package management with pip, virtual environments, project organization, and version control with Git. These skills are crucial for developers to share and deploy their work effectively.To address this, a free, self-paced 6-week course called Ship Your First Python App has been created. The course aims to teach the complete local development workflow from the ground up. Participants will build a small command-line application: a dev journal. Each week introduces new concepts and culminates in a failing test suite that students must resolve.The curriculum covers project setup, data modeling, command-line interfaces, type safety, error handling, code organization, testing, improving output formatting, and measuring test coverage. The final week focuses on preparing the project for sharing, including writing documentation and potentially publishing it to PyPI. This course is designed for individuals who understand basic Python but struggle with the surrounding development processes. It assumes no prior knowledge of CLIs, packaging, or Git, making it accessible to a wider audience. The creator is actively seeking feedback to improve the course's utility and user experience.
This text describes the creation of a JupyterLab workshop focused on teaching pytest. The workshop is designed to be small enough to fit within a blog post but contains all essential elements of a real workshop. It includes a manifest, multiple pages, interactive actions, automatic checks, a quiz, and supporting tools. The workshop teaches the fundamental pytest loop: writing a test, observing its failure, and then fixing the code. This iterative process is structured across four distinct pages within the workshop. A key feature is the creation of an isolated Python environment for the workshop, ensuring pytest is installed without affecting the learner's system. This approach leverages content lessons from a previous conference talk to enhance the learning experience. The process begins with planning and defining verifiable steps, distinguishing workshops from tutorials. The workshop is generated using the jupyter workshop init command, which sets up the directory structure and a manifest file. Capabilities like terminal access, file writing, code execution, and package installation are declared in the manifest, and are verified by linters. The environment field in the manifest specifies dependencies, such as pytest, which are installed into a self-contained virtual environment. This avoids manual environment setup, allowing learners to focus on pytest itself. The env entry in the manifest also disables Python bytecode caching to prevent issues with rapid file modifications. The workshop utilizes a files/orders.py file containing a deliberately buggy function for learners to debug. Each page in the workshop uses Markdown and specific action blocks to guide the learner through tasks like opening files, writing code, and running commands. Checks are implemented using the verify action, which automatically validates the outcome of learner actions, ensuring progress and learning. A quiz action is included to prompt learners to predict outcomes before running tests, reinforcing understanding of how pytest behaves. The editor-insert action allows new code, like tests, to be added and viewed directly in the editor. The workshop's structure and content are designed to be interactive and educational, focusing on practical application of pytest.
CdXz5zHNQW_hkEwNEOUhk.png
The author was designing a shared contract for a CLI tool interacting with two different image-generation backends. The goal was to allow the CLI to use a generic submit(request) function, with each backend translating it into its own SDK calls. Initially, the author considered using abstract base classes (ABCs) as a shared interface due to their enforcement of abstract methods. However, ABCs require inheritance, which creates coupling for third-party pluggable backends.Typing.Protocol emerged as a better fit because it uses structural typing. A class satisfies a Protocol by having the correct methods with the right signatures, without requiring explicit inheritance. This approach decouples outside implementers from the core package, allowing providers to evolve independently. Protocols promote a composition-based design, where a provider is passed as a value rather than being part of a strict hierarchy.While Protocols are ideal for describing plugin boundaries, ABCs are more suitable when providers need to share concrete behavior or implementation logic. An ABC can define shared methods and enforce abstract methods that concrete subclasses must implement. It's also possible to use both: a Protocol for the public plugin boundary and an internal ABC for shared behavior among providers.The author recommends defaulting to Protocol for its lighter contract, switching to ABC only when shared implementation is necessary or when runtime enforcement of abstract methods is desired. For plugin ecosystems, "conform by shape" (Protocol) is often preferable to "conform by inheritance" (ABC). The choice depends on whether the primary need is to define a shape or to share concrete behavior and enforce a hierarchy.
CdXz5zHNQW_cy1larHnBn.png
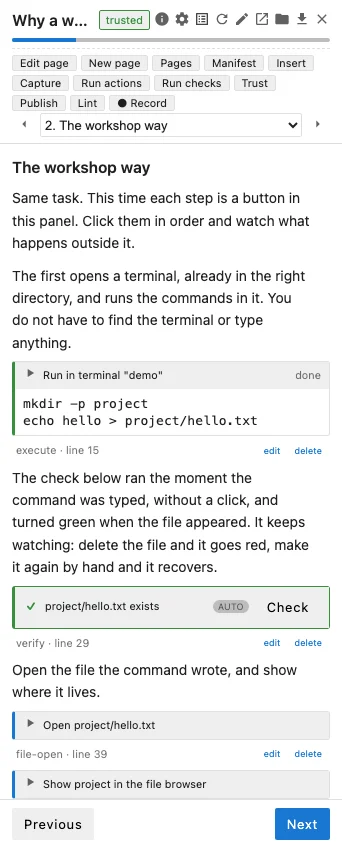
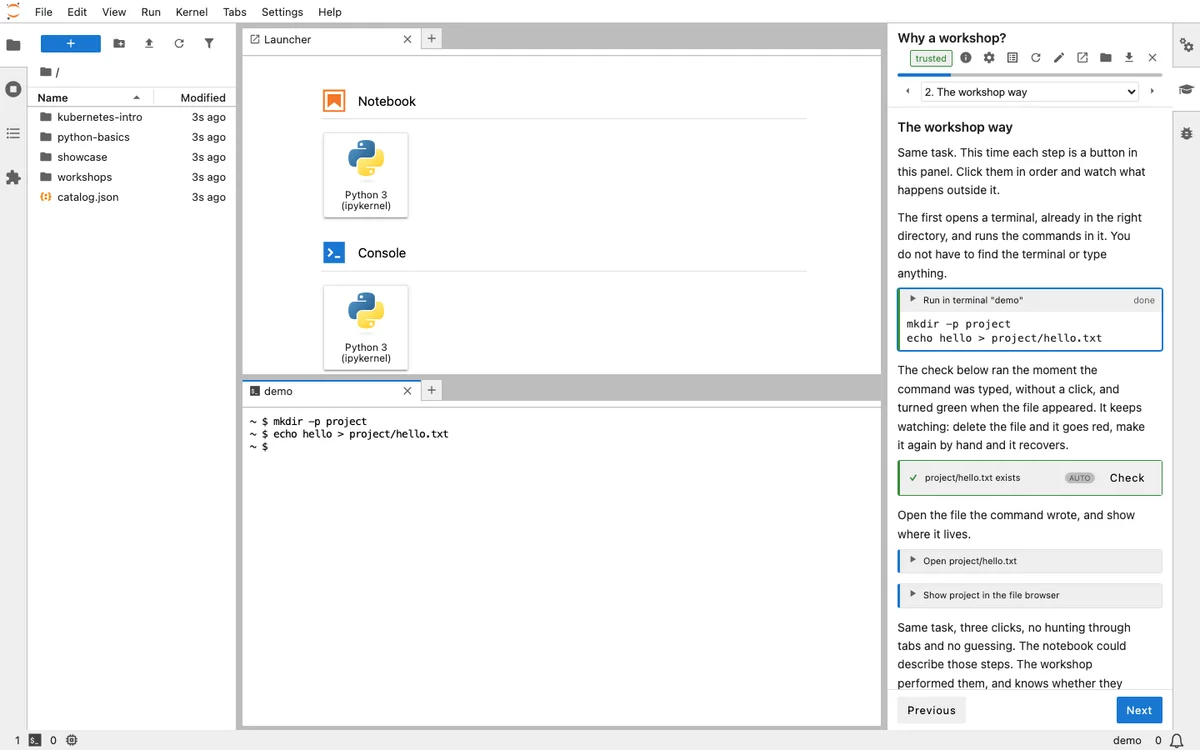
The author developed jupyterlab-workshop, a JupyterLab extension, to address limitations in using plain Jupyter notebooks for educational workshops. This extension separates instructions from the actual work to be done by the learner. Instructions are presented in a sidebar panel, with each step being an actionable item within the JupyterLab environment. These actions can include running terminal commands, modifying files, creating notebooks, and executing code. The workshop can also verify learner progress and enforce task completion before allowing them to proceed.Unlike notebooks where learners might passively watch code execute, this extension ensures active participation as actions are performed in real-time. It overcomes the constraint of notebooks being limited to a single language by enabling interaction with the broader JupyterLab environment and external tools. This separation prevents the conflation of instructional content and completed work, offering a clearer learning path. The sidebar panel provides navigation, progress tracking, and details of performed actions.Each executable step is not simulated; clicking an action executes it in a live terminal or performs the designated task. The extension supports various actions, including terminal operations, file management, notebook interaction, and interface manipulation. Workshops can even be designed to arrange the user interface for optimal learning at specific points. Checkpoints allow learners to save their progress and revert to a known state if errors occur.The extension includes a robust verification system, allowing for checks through Python code, shell commands, or file-based predicates. Quizzes can also be integrated, with answers feeding into subsequent steps. The manifest file dictates whether task completion is advisory or mandatory. Security is addressed through a trust mechanism where learners grant specific capabilities to workshops before execution.A workshop itself is structured as a directory containing a manifest file, Markdown files for pages, and any necessary starter files. This plain-text structure facilitates version control. Pages are written in MyST Markdown, with actions defined in fenced code blocks. The extension can be installed locally or used via services like mybinder.org and GitHub Codespaces, allowing workshops to run in various environments without complex setup. The author chose not to use their previous platform, Educates, because it required Kubernetes, limiting its accessibility for smaller teams and individuals.
CdXz5zHNQW_ghHpRchT3T.png
A new Rust student encountered an error when trying to call read_to_string on a File object. The compiler indicated that no such method existed. The solution involved adding use std::io::Read; at the beginning of the file. This import confused the student, who expected std::io::File to be imported if file operations were intended.The core of the confusion lies in Rust's trait system. The read_to_string method is not an inherent method of the File type itself. Instead, it's defined by the Read trait, which File implements. Importing the Read trait makes its methods available for method lookup by the Rust compiler.This mechanism differs significantly from Python, where method availability is typically tied directly to the object's type. In Rust, traits provide a way to define shared behavior across different types, promoting polymorphism and code reuse. For instance, File, TcpStream, and Stdin all implement the Read trait, allowing them to offer similar reading functionalities.Therefore, use std::io::Read; isn't about directly using a function but about bringing the Read interface into scope. This allows the compiler to consider the Read trait when resolving method calls on types that implement it. Understanding traits is crucial for comprehending why certain seemingly unrelated imports are necessary for method functionality in Rust. This approach avoids code duplication and enables generic programming. The compiler's error message, "trait Read is implemented but not in scope," directly points to this trait resolution issue.
CdXz5zHNQW_hpByPwlbht.png
The speaker discusses the relevance of developer workshops in the age of AI, noting that AI excels at providing step-by-step guides and tutorials. However, the core value of workshops lies in active learning through doing, where mistakes have consequences and require problem-solving. This hands-on struggle deepens understanding in ways passive reading or AI-generated explanations cannot replicate. Furthermore, workshops expose learners to issues they might not have anticipated, a crucial aspect for real-world development.The effectiveness of workshops depends on overcoming common pitfalls: environmental setup issues, overly large steps, insufficient explanation of "why," and inadequate verification. The speaker advocates for hosted environments that standardize the starting point for all participants, enabling better support and more complex learning scenarios. While AI can assist in drafting workshop content, it falters in understanding the human learning process. AI optimizes for correctness, not teachability, and cannot anticipate learner confusion.The critical step in workshop creation is testing with real people, as AI-generated material often reads well but fails in practice. The pressure from AI is most acutely felt in voluntary learning scenarios driven by curiosity, as AI can satisfy that curiosity more efficiently and at no cost. However, workshops with a clear business driver, like sales demos or customer training, remain highly relevant. Ultimately, workshops are about fostering a learning rhythm that AI cannot fully replicate.
The idea that AI will cause humanity's extinction has recently gained traction. Some AI leaders, like Dario Amodei, estimate a significant probability of such an event. Amodei's post about pacing AI development has sparked discussion among prominent figures. However, the author disagrees with the premise, despite sharing many concerns.The author defines "doom" not as extinction, but as persistent nuisances like botnets, where AI systems become difficult to control. They acknowledge that current AI systems are annoying but can be shut down, unlike potential future advanced agents. The author worries about the impact of AI on individuals outside of major AI labs, rather than existential threats like AI-controlled weapons.The concept of "pacing" AI development is seen as problematic, especially since only a few American companies are leading this race. These companies benefited from public data and resources and now propose third-party evaluation systems tied to them. The author criticizes the idea that only these corporations should control powerful AI, especially considering their geopolitical motivations.Open-weight models, the author argues, would inherently pace AI development through widespread accessibility, similar to nuclear proliferation. The current situation, where the public supports AI development but buys back its benefits from a few labs, is seen as a flawed economic and geopolitical model. While open-source projects are strained by AI companies, Chinese labs are seen as crucial for diffusing capabilities and leveling the playing field.The author points to a regulatory failure, with existing laws being ignored and data being used without consent. The emergent token economy for AI services is likened to a drug market, lacking transparency. Ideally, AI development should have benefited the public commons, with regulations mandating support for distillation of knowledge.Ultimately, the author does not foresee an AI extinction event, believing that large labs would have more to lose. Instead, the primary concern is the widespread damage AI could cause to various industries, making them more expensive. This new "tax" on innovation, evident in software engineering, is expected to spread to other fields as well.
Wrapture now integrates OpenTelemetry as a first-class destination for tracing data. The wrapture.otel subpackage, included with every installation, enables seamless export to tracing backends. By adding an [otel] table to the configuration, users can enable tracing, specify a service name, and tune individual signal settings. This configuration allows for detailed introspection into application behavior, including errors and request details.OpenTelemetry environment variables dictate where tracing data is sent, with console exporters available for immediate debugging. Each application event is translated into a span, forming a hierarchical trace. For instance, a Flask request becomes a server span, with internal calls creating nested spans. Error conditions, like a KeyError, are accurately captured with status codes and exception details.The instrumentation automatically captures arguments and other annotated data as span attributes, with sensitive information like credit card numbers being redacted. This ensures that errors are fully documented, appearing on both the specific operation and the parent request span. Distributed tracing across multiple processes is achieved through W3C trace context propagation.Wrapture injects trace context headers into outgoing requests, which are then parsed by the receiving service's middleware. This allows traces to span across different services, maintaining a consistent trace ID. Even when OpenTelemetry export is enabled, wrapture preserves its own minted trace IDs, ensuring continuity.Metrics are also generated from the same traced events, providing aggregated insights without requiring explicit instrumentation code changes. Request durations and call durations are automatically collected and attributed by relevant information like HTTP methods, routes, and status codes. These metrics offer valuable performance and error rate information.The overhead of using wrapture with OpenTelemetry is comparable to direct OpenTelemetry SDK usage. Wrapture optimizes span processing by building finished spans directly, bypassing some of the SDK's internal overhead. This results in lower costs, especially for operations that raise exceptions.The core principle behind wrapture's design remains consistent: correctly observing real-time calls for both testing and production tracing. Whether feeding a testing tape or a tracing backend, the underlying mechanism remains the same. The OpenTelemetry export page provides further details on advanced features like sampling and log signal integration.
The Flask shop's /order endpoint is slow, and the goal is to identify the bottleneck. Traditional stopwatch methods require code changes, produce unlinked log lines, and struggle with intermittent slowness. Profilers offer too much detail, obscuring request-specific information.Using the existing config, initial tracing immediately reveals a breakdown of times. The request takes 37.3ms, the view 36.3ms, the service 35.9ms, and the ledger 35.1ms, while the gateway is only 8us. This indicates the ledger is the primary cause of slowness.The concept of "self time" distinguishes operations that are slow themselves from those slow due to their children. Wrapture computes this, showing the ledger is slow in its own right, while the service and view are slow because they call the ledger.A test using wrapture.instrumentation and wrapture.timeline confirms this: the OrderService.place has a self time of 173us out of 31.0ms, while Ledger.record accounts for most of the duration. This level of detail is unavailable from standard profilers.For long-term monitoring, the Aggregate collector gathers statistics across many requests, including total, self, min, and max times. A report from sending thirty requests to the server confirms Ledger.record as the top contributor by self time.To track slowness per tenant, wrapture.annotate allows adding custom data like "X-Tenant" to in-flight events. This enables filtering traces to identify which tenants experience slower requests.The Counter collector provides a cheaper alternative, only counting operations without retaining durations, suitable for budget-based assertions in test suites (e.g., detecting N+1 query problems). The next step is feeding these events to a tracing backend.
This project implements a FastAPI service with granular role-based access control (RBAC) using Azure Entra ID for authentication. Instead of hardcoding access policies into each route, these policies are stored in a database table. This allows administrators to change user permissions without modifying and redeploying the application code. The system uses Azure Entra ID to authenticate users and retrieve their roles from JWT claims. A mapping of endpoint keys to required roles is stored in an EndpointPermission SQLModel table.The core of the authorization logic lies in a require function, which is used as a FastAPI dependency. This function retrieves the required roles for an endpoint from the database and checks if the authenticated user possesses any of them. If not, a 403 Forbidden error is raised. The key string for an endpoint is the only literal hardcoded in its route definition.Critically, the endpoint for managing these permissions is itself protected by the same RBAC mechanism, ensuring only administrators can modify access rules. Safeguards prevent administrators from accidentally revoking their own access to the permission management endpoint and ensure that role assignments are never empty. The article highlights two common Azure configuration issues: using v1 tokens instead of v2, which causes invalid token errors, and the fact that nested group memberships are not reflected in user roles for direct assignment.The project also provides guidance on testing the authorization logic effectively. Tests can override the authentication and session dependencies to use fake users and in-memory SQLite databases, allowing for comprehensive testing without external dependencies. This design, by externalizing policy as data, makes authorization dynamic and manageable, aligning with the 12-factor app principle. The author emphasizes distinguishing between code logic and changeable policy.
This issue of PyCoder's Weekly covers a range of topics for Python developers. It features a discussion on profiling and making Python applications fast by default, aligning with Den Odell's new book, "Fast by Default." Another key article addresses migration strategies from pandas to Polars, including LLM-assisted full pipeline migration. There's also an announcement about PR-AF, an open-source code reviewer, performing exceptionally well on Code-Review-Bench.Several articles delve into practical Python usage, such as when to use NotImplemented in dunder methods and building a plugin architecture with Pydantic and FastAPI. An important update from PyPI.org specifies that metadata requests are no longer counted as package downloads, improving download statistics accuracy. Tutorials offer guidance on building face recognition tools and fixing common "NoneType" object errors.Other educational content includes a primer on Python decorators and insights into testing async Python effectively. Developers can also learn about storing Django static and media files on Cloudflare R2. Thought-provoking pieces like "Analysis Paralysis Sucks" and "Why OOP Exists" offer broader development perspectives.A preview of Python 3.15 highlights the default UTF-8 encoding change, with a corresponding quiz. The issue also includes projects like Shedskin, a Python-to-C++ transpiler, and Pandas-silent-bugs, showcasing numerous examples of errors in pandas. Upcoming events for the Python community in September 2026 are also listed, including various meetups and PyCon Cameroon.
CdXz5zHNQW_IGTZIgus4k.png